

Executive Overview
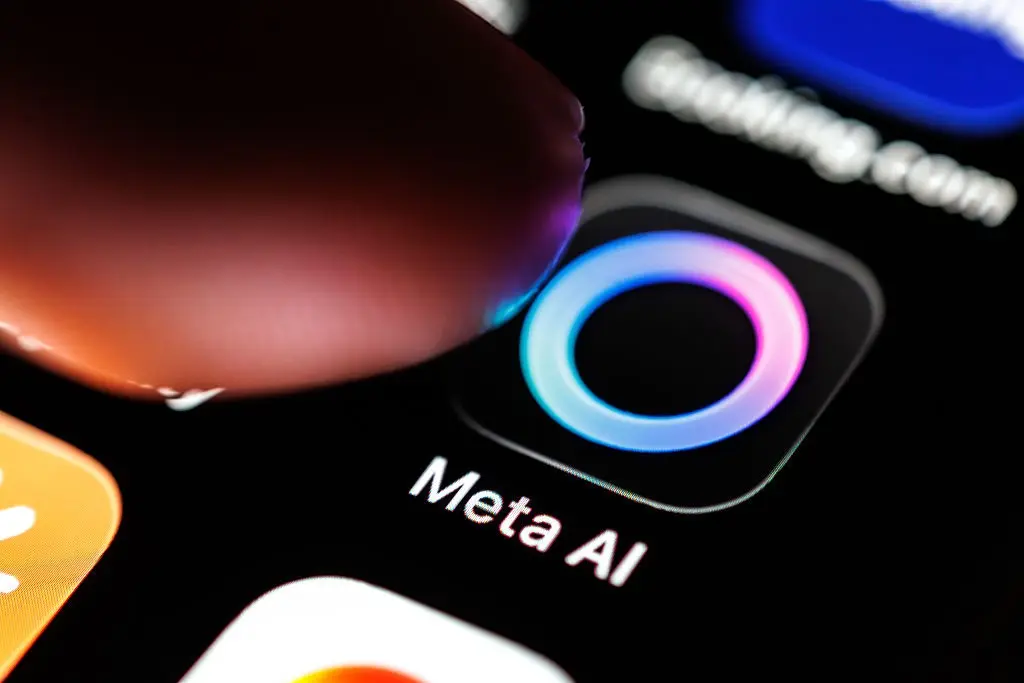
In the rapidly evolving digital landscape where artificial intelligence intersects with intellectual property rights, few battles are as fiercely contested as the debate over web scraping. Recently, tech giant Meta found itself at the epicenter of a fresh controversy after updating its commercial terms of use. The revised policy appeared to grant the corporation sweeping authorization to harvest content from any domain, webpage, or URL linked to a business account. According to prominent legal scholars and digital rights advocates, the ambiguous language effectively licensed Meta to ingest proprietary journalism, copyrighted creative works, and commercial data en masse to train its proprietary large language models.
The revelation sparked immediate alarm throughout the publishing industry, already on high alert amid ongoing legal confrontations regarding generative AI training practices. Legal analysts contacted by digital media watchdogs described the clause as a "remarkable provision," one that threatened to bypass traditional licensing negotiations by leveraging commercial account registries as legal pretexts for unrestricted data harvesting.
Faced with mounting scrutiny, vocal pushback from the media community, and the looming specter of further antitrust and copyright litigation, Meta swiftly recalibrated. Following public assurances from corporate representatives that the policy had been misinterpreted, the company executed a quiet retreat, scrubbing the contentious phrasing from its official terms of service. While Meta maintains that the update was merely a consolidation of legacy guidelines intended exclusively for advertising and business analytics products rather than AI ingestion, the episode underscores the profound fragility of trust between platform gatekeepers and content creators. This in-depth investigative report examines the chronology of the policy shift, the broader legal battles defining the AI era, the competing official statements, and the long-term implications for the publishing ecosystem.
Detailed Chronology of a Policy Controvery
To understand the gravity of Meta’s recent policy maneuvers, one must trace the timeline of events that transformed a routine administrative update into a major industry-wide flashpoint.
The Silent Rollout
The controversy began when Meta initiated a broad restructuring of its commercial terms of use. These legal frameworks govern how businesses, advertisers, and publishers interact with Meta’s sprawling ecosystem, which includes Facebook, Instagram, WhatsApp, and specialized enterprise tools. Buried within the dense legalese of the updated agreement was a newly phrased mandate. The text explicitly declared that the company reserved the right to "use any content from [a business account’s] domains, web pages, or URLs to provide, develop, improve, research, train, and maintain the integrity of" Meta’s suite of products and services.
For casual observers, terms of service updates are frequently dismissed as bureaucratic boilerplate. However, legal experts specializing in media and technology law immediately recognized the profound implications of the phrasing. By tying the permission to a business account’s associated domains and URLs, Meta appeared to be establishing a contractual mechanism that bypassed standard web crawling protocols. Publishers who maintained a business presence on Meta platforms—a near-necessity for audience acquisition and digital distribution in the modern media economy—might inadvertently be signing away the rights to their proprietary content for AI training purposes.
The Alarm is Sounded
The implications of the clause were first brought to light by legal scholars and analysts, most notably through investigative coverage by Nieman Lab. Experts interviewed for the report characterized the provision as unprecedented in its breadth. Rather than relying on traditional public web crawling—which publishers can technically block via robots.txt files or restrict through paywalls—the new commercial terms introduced a contractual back door.
The concern was twofold. First, it created a structural trap for publishers who depended on Meta for traffic referral but could not afford to opt out without sacrificing essential marketing reach. Second, it provided Meta with a legal shield against copyright infringement claims. If a publisher agreed to the commercial terms as a condition of maintaining a business page, Meta could theoretically argue in a court of law that the subsequent ingestion of site content was fully authorized by contract, thereby neutralizing traditional copyright defenses.
Public Defense and Rapid Retreat
As the story gained traction across technology and media trade publications, Meta attempted to stem the tide of negative publicity. A company spokesperson took to social media to push back against the burgeoning narrative, insisting that the updated terms did not represent a functional shift in how Meta crawls or indexes the open web.
Despite these early assurances, the pressure continued to mount. The intersection of generative AI and copyright law is a sensitive terrain, and publishers—many of whom are already party to class-action lawsuits against major tech firms—were in no mood to grant sweeping concessions.
Recognizing the untenable nature of the PR crisis and the potential legal exposure, Meta took definitive action. As reported by The Verge, the company quietly removed the contentious language from its commercial terms of service. The offending sentences regarding the training of Meta products using domain-level content were excised, replaced with narrower, more traditional definitions of data usage strictly confined to ad delivery and business product functionality.
Supporting Context & Metrics: The Broader AI Copyright War
Meta’s sudden pivot cannot be viewed in isolation. It occurs against the backdrop of an unprecedented legal and economic war between content creators and artificial intelligence developers. As generative AI models require vast quantities of high-quality human-generated text, images, and video to achieve conversational and analytical competence, tech companies have engaged in aggressive data acquisition strategies.
The Legal Landscape
For years, AI developers operated under the assumption that scraping publicly accessible web pages fell under the legal doctrine of "fair use." However, that assumption is being aggressively tested in courts across the globe.
- The Book Publishing Precedent: Meta is no stranger to the courtroom regarding these matters. Late last year, the company successfully defended itself in a high-profile federal lawsuit where authors alleged that Meta unlawfully utilized copyrighted books to train its Llama models. A federal judge ultimately sided with Meta, ruling that the training process constituted transformative use under existing copyright frameworks.
- The Ongoing Publisher Offensives: While the book industry suffered a setback in that specific ruling, the news publishing sector has proven far more litigious and coordinated. Earlier this year, a coalition of major media publishers filed a landmark lawsuit against Meta, alleging widespread, unauthorized copyright infringement stemming from AI training models. Similar sweeping legal actions have targeted OpenAI, Google, Microsoft, and Anthropic.
The Economic Dilemma for Publishers
The economic stakes for the publishing industry are existential. For decades, traditional media outlets have relied on a symbiotic yet tense relationship with social media platforms. Platforms provided the distribution pipe; publishers provided the trusted journalism that kept users engaged. However, the rise of generative AI threatens to invert this dynamic entirely.
When AI models scrape news sites, synthesize the reporting, and present the information directly to users via conversational search or in-app assistants, the incentive for users to click through to the original publisher’s website evaporates. This "zero-click" reality starves publishers of essential advertising revenue and subscription conversions. Consequently, publishers view unrestricted web scraping not merely as a technical annoyance, but as an existential threat to their financial viability. By attempting to codify scraping rights into commercial terms of use, Meta inadvertently touched the rawest nerve in the modern media economy.
Official Statements and Corporate Communication
In the wake of the policy rollback, Meta has sought to project absolute clarity and transparency regarding its intentions. The company’s official communication strategy hinges on the assertion that the entire controversy was the result of a linguistic misunderstanding rather than a nefarious shift in data strategy.
In a formal statement released to media outlets following the removal of the clause, Meta explained:
"We’ve heard you and want to clarify: the crawling terms we consolidated only applied to our ads and business products, and we’ve clarified that in the terms themselves. It does not change how Meta uses web crawlers."
According to this narrative, the legal team responsible for drafting the updated terms was merely attempting to streamline a labyrinthine set of legacy agreements governing how business data, pixel tracking, and ad performance metrics are processed. In doing so, however, they inadvertently imported language that conflated commercial analytics with foundational AI model training.
Independent legal observers remain skeptical of this benign interpretation. Drafting corporate legal terms of this magnitude involves multiple layers of review, and specific inclusions regarding model "training" and product "development" are rarely accidental. Nevertheless, the speed with which Meta capitulated and removed the language suggests that the corporate risk assessment concluded that the public relations and legal fallout outweighed any potential benefits of retaining the clause.
Future Outlook: What Lies Ahead for Tech and Publishing
The swift addition and subsequent removal of Meta’s controversial scraping terms serves as a bellwether for the future of digital content, intellectual property, and artificial intelligence development. As we look toward the horizon, several key trends and trajectories are likely to define the relationship between tech platforms and content creators.
1. Increased Scrutiny on Terms of Service
Publishers, legal watchdogs, and regulatory bodies will undoubtedly maintain heightened vigilance regarding the fine print of tech platform agreements. The era of blindly clicking "Accept" on updated terms of service is officially over for corporate entities. Legal departments across the media landscape will employ automated monitoring tools to scan for subtle shifts in data ownership, licensing provisions, and AI training clauses.
2. The Rise of Content Licensing Ecosystems
As unilateral scraping becomes legally and politically perilous, the industry is gradually shifting toward formal licensing agreements. Major news conglomerates have already forged multi-million-dollar data-sharing pacts with AI giants like OpenAI and Google. However, a significant digital divide remains: while tier-one global publications can negotiate lucrative licensing deals, smaller, independent, and regional publishers lack the legal muscle to secure favorable terms. Meta’s retreat suggests that finding a standardized, equitable mechanism for compensating all creators remains an unsolved puzzle.
3. Technological Countermeasures: The Arms Race
Beyond the courtroom and the conference room, the technical battle over web access is intensifying. Publishers are increasingly deploying advanced bot-blocking infrastructure, dynamic paywalls, and sophisticated robots.txt directives to lock out unauthorized scrapers. In response, AI companies are developing more stealthy crawling techniques, utilizing decentralized residential proxy networks to mimic organic human traffic. The removal of Meta’s contractual clause does not halt web scraping; it merely forces the practice back into the murky technical gray areas of the open web, away from the explicit accountability of contractual terms.
4. Regulatory Interventions on the Horizon
Governments and regulatory bodies worldwide are waking up to the systemic risks posed by unchecked AI data harvesting. Antitrust authorities and copyright offices in the European Union, the United States, and beyond are actively investigating whether the ingestion of copyrighted works for generative AI training violates existing statutory protections. Episodes like Meta’s policy pivot provide regulators with concrete examples of how major tech platforms attempt to adjust legal frameworks to suit their technological ambitions, further fueling the legislative push for mandatory transparency and fair compensation frameworks.
Conclusion
Meta’s recent about-face on its commercial terms of use is a microcosm of the profound friction defining the digital age. It highlights the aggressive push by technology conglomerates to secure the raw materials necessary for artificial intelligence supremacy, contrasted against the fierce, protective resistance of an intellectual property ecosystem fighting for its economic survival.
While Meta has successfully defused this particular crisis by excising the contentious language from its agreements, the underlying tensions remain entirely unresolved. The fundamental question of who owns the data that fuels the intelligence revolution is far from settled. As ongoing lawsuits wind their way through the courts and publishers fortify their digital defenses, the delicate truce between platform gatekeepers and content creators will continue to be tested, leaving the future of digital journalism hanging in the balance.
Belum ada komentar. Jadilah yang pertama berkomentar!