

By Russell Brandom
Technology & Platform Policy
Executive Overview
In a definitive escalation of the artificial intelligence wars, Meta’s Superintelligence Lab has officially pulled back the curtain on its first true frontier models: Muse Wonder and Muse Wonder Full. Released on Monday, this powerful new tandem represents a watershed moment for the tech giant, shifting its strategic focus from lightweight efficiency toward heavy-duty, state-of-the-art capability.
Where its predecessor, Muse Spark, was deliberately engineered as a nimble, low-latency utility, the Wonder models are built for absolute computational muscle. According to official model cards and internal benchmarks published by Meta, Wonder and Wonder Full trade blows with industry heavyweights like Fable 5.1 and GPT-6 Astra. They excel notably in complex, multi-step workflows such as advanced software engineering and dynamic reasoning.
Described by the company as a major stride on its “scaling ladder,” the release underscores Meta’s aggressive ambition to transition from social media titan to the foundational architect of personal superintelligence. Yet, the launch is notable not only for its raw performance metrics, but for its architectural emphasis on long-term memory. By introducing a groundbreaking framework known as “active memory,” Meta is attempting to solve one of the industry’s most persistent hurdles: building an AI assistant that actually remembers your life across days, weeks, and months.
Trained at Meta’s newly operational Prometheus data center in central Ohio—a facility boasting some of the highest computing capacities in the world—these models mark the first major frontier rollout under the leadership of Scale AI founder Alexandr Wang. As pricing structures solidify, API limitations take shape, and benchmarks redefine what is possible in memory retention, Meta’s latest release signals that the battle for the future of consumer AI has officially entered a new phase.
Detailed Chronology: From Restructuring to the Prometheus Debut
To understand the magnitude of the Muse Wonder release, one must trace the timeline of Meta’s internal AI reorganization over the past year.
For much of the generative AI boom, Meta positioned itself as an open-source champion via its Llama series, while simultaneously cultivating massive internal infrastructure. However, the corporate strategy underwent a seismic shift in August of last year when Scale AI founder Alexandr Wang was brought in to overhaul Meta’s sprawling AI development pipeline. Wang’s mandate was clear: streamline fragmented research efforts, accelerate time-to-market for elite-tier capabilities, and position Meta to directly challenge the closed-ecosystem dominance of competitors like OpenAI and Anthropic.
In the months immediately following Wang’s restructuring, Meta played a measured game. It rolled out the lightweight Muse Spark model alongside the consumer-facing Muse agent, focusing on swift user interactions and low operational costs. While these releases proved popular, industry critics noted that Meta had deliberately avoided the high-stakes, state-of-the-art model rollouts that defined the cutting edge of AI development.
The silence was broken this week with the deployment of Muse Wonder and Muse Wonder Full. According to technical disclosures accompanying the launch, the training ground for these heavy-hitting models was none other than the Prometheus data center in New Albany, Ohio. First announced as a high-capacity regional infrastructure project, the Prometheus facility officially came online earlier this year, serving as the crucible for Meta’s next-generation compute loads. The synergy between Prometheus’s raw processing power and the engineering frameworks developed under Wang’s leadership has finally yielded Meta’s long-awaited debut in the frontier model arena.
Supporting Context & Metrics: Benchmarks, Pricing, and Architecture
The release of the Muse Wonder models brings with it a complex matrix of performance data, pricing structures, and ecosystem integrations that separate casual developers from enterprise-grade deployment.
Benchmarking the Frontier
Meta’s testing reveals that Muse Wonder and Muse Wonder Full are competitive with, and in certain domains superior to, established market titans. On standard coding, logic, and general reasoning benchmarks, the models match the performance profile of Fable 5.1 and GPT-6 Astra.
However, Meta’s most striking performance claim lies in its proprietary focus on memory construction and continual learning. To evaluate this capability, Meta utilized MemoryBench—a rigorous testing framework designed to challenge an AI’s capacity to ingest, store, synthesize, and recall vast repositories of user-specific data over extended interaction horizons. According to the model card data, Muse Wonder outscores Fable, Opus, and Astra on MemoryBench, establishing a new high-water mark for contextual persistence.
Pricing and Access Tiers
Scaling power demands serious capital, and that economic reality is reflected in how developers and consumers will access the new technology:
- Muse Wonder via Meta Model API: Available to third-party developers, Wonder is priced at $4 per million input tokens and $20 per million output tokens. This positions it squarely in line with competitive frontier offerings such as GPT-6 Sol and Opus 5.5.
- Muse Wonder Full (The Flagship Tier): In an unexpected distribution move, the hyper-capable Wonder Full model will not be accessible via the standard Meta Model API. Instead, it is being sequestered exclusively as a benefit for Muse Code subscribers, while also serving as the underlying engine for the flagship Muse consumer agent.
The Innovation of “Active Memory”
The core differentiator for the Wonder series is Meta’s obsession with what it terms “active memory.” Traditional large language models operate within a fixed context window, often forgetting granular details once a conversation thread grows too long or is reset. Meta’s approach combines continuous learning architectures with optimized retrieval systems designed to mimic human long-term retention.
By prioritizing active memory, Meta is directly addressing the fatigue users experience when repeatedly having to re-explain their preferences, workflows, and personal contexts to AI assistants.
Official Statements and Industry Commentary
Meta’s leadership has wasted no time framing the Muse Wonder release as a historical turning point for the company.
In an official corporate blog post accompanying Monday’s launch, the company did not mince words regarding its overarching trajectory:
“Together, they mark the next step on our scaling ladder and a major leap toward personal superintelligence.”
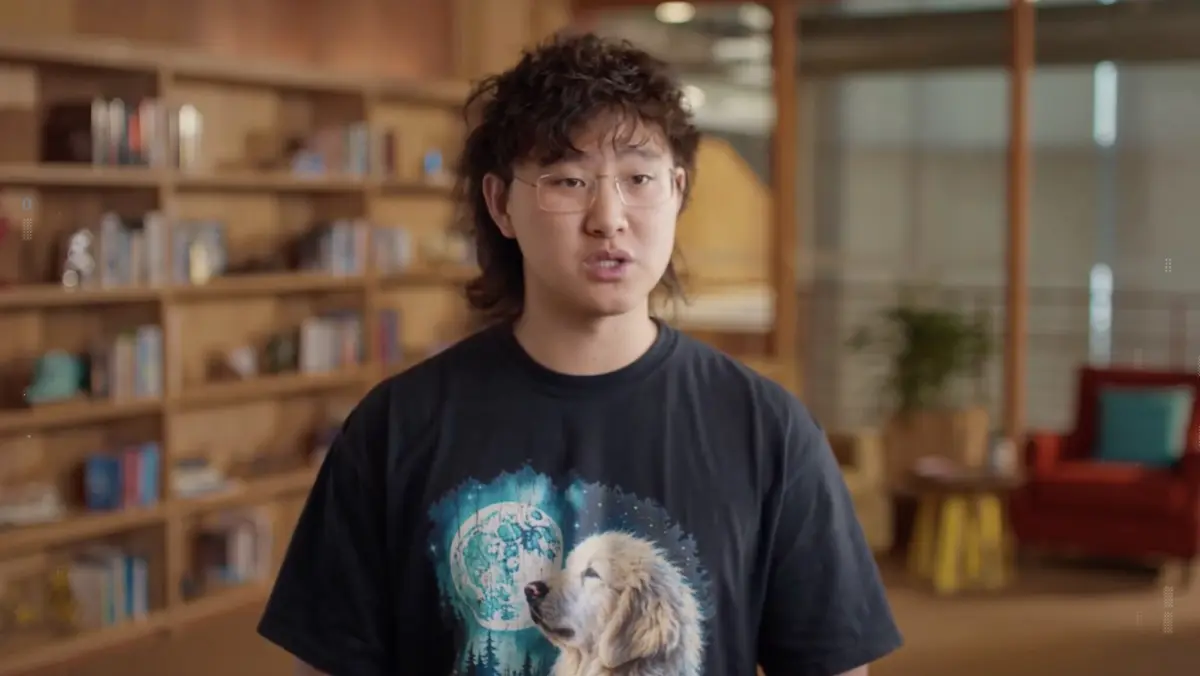
The strategic shift is designed to transform the AI assistant from a reactive search tool into a proactive, long-term companion. In a video presentation detailing the engineering philosophy behind the models, research scientist Kavya Kopparapu emphasized the human-centric design choices that went into the architecture:
“We put a tremendous amount of effort into making sure your model can remember what’s important to you over days, weeks, months, and beyond.”
Independent industry analysts have noted that by locking Muse Wonder Full behind the Muse Code subscription tier, Meta is attempting a two-pronged strategy: capturing high-margin enterprise developer revenue through the API via the standard Wonder model, while aggressively driving consumer and specialized developer subscriptions through its proprietary agent ecosystem.
Future Outlook: The Road to Personal Superintelligence
As the dust settles on the initial launch announcements, the tech industry is left to evaluate the broader implications of Meta’s entrance into the frontier race.
The release of Muse Wonder and Muse Wonder Full signals that the era of lightweight, utility-only models is giving way to deeper, more integrated agentic systems. By solving the persistence problem through active memory, Meta is laying the groundwork for AI assistants that do not merely answer questions, but manage workflows, execute multi-day tasks, and maintain an evolving digital understanding of their users.
However, challenges remain. Restricting the flagship Wonder Full model to Muse Code subscribers rather than opening it universally via API may frustrate independent developers looking to build on top of Meta’s absolute best infrastructure. Furthermore, as competitors like OpenAI, Anthropic, and Google inevitably respond with their own counter-releases, Meta will need to prove that the Prometheus data center can sustain rapid iteration cycles without compromising safety or reliability.
For now, the gauntlet has been thrown down. Meta has officially transitioned from a follower in the frontier model space to a frontrunner, and the race toward personal superintelligence has accelerated into hyperdrive.
Belum ada komentar. Jadilah yang pertama berkomentar!